Anthropic
Previous Opus-tier flagship retained for compatibility after newer Claude Opus releases. Still strong on deep reasoning, extended thinking, and advanced coding, but superseded by Claude Opus 5 for Anthropic's latest Opus-tier performance.
Still strong on deep reasoning, extended thinking, and advanced coding, but superseded by Claude Opus 5 for Anthropic's latest Opus-tier performance.
Current rates are not verified. Missing pricing does not mean free usage.
Confirm this specific model, usage limits, and billing terms with the provider. A subscription does not automatically include API credits.
No login needed to compare. Prices are in USD; provider charges are separate from AI Market Cap plans. Context length, caching, tools, taxes, and regional terms can change the final cost. Open weights do not mean free hosting.
20.8
Quality Score
---
Arena ELO
Undisclosed
Parameters
200K
Context
This measures the amount of verifiable public evidence we have, not how capable the model is. A missing field means it has not been verified yet, not that its value is zero.
16 of 22 public signals
Sign in to join the discussion
0
Downloads
0
Likes
Aug 2025
Released
4/5 signals
3/4 signals
4/5 signals
1/4 signals
4/4 signals
Parameters
—
Training compute
Not reported
Dataset scale
Not reported
Base model
Not reported
Source-reported access: API access · Unknown confidence
Gaps we are still tracking
Launches
3
Benchmarks
5
Open Source
1
Safety
1
Research
1
General
5
Recent launch, pricing, benchmark, and API signals linked to this model or its provider.
SWE-Bench Verified resolved rate 76.8
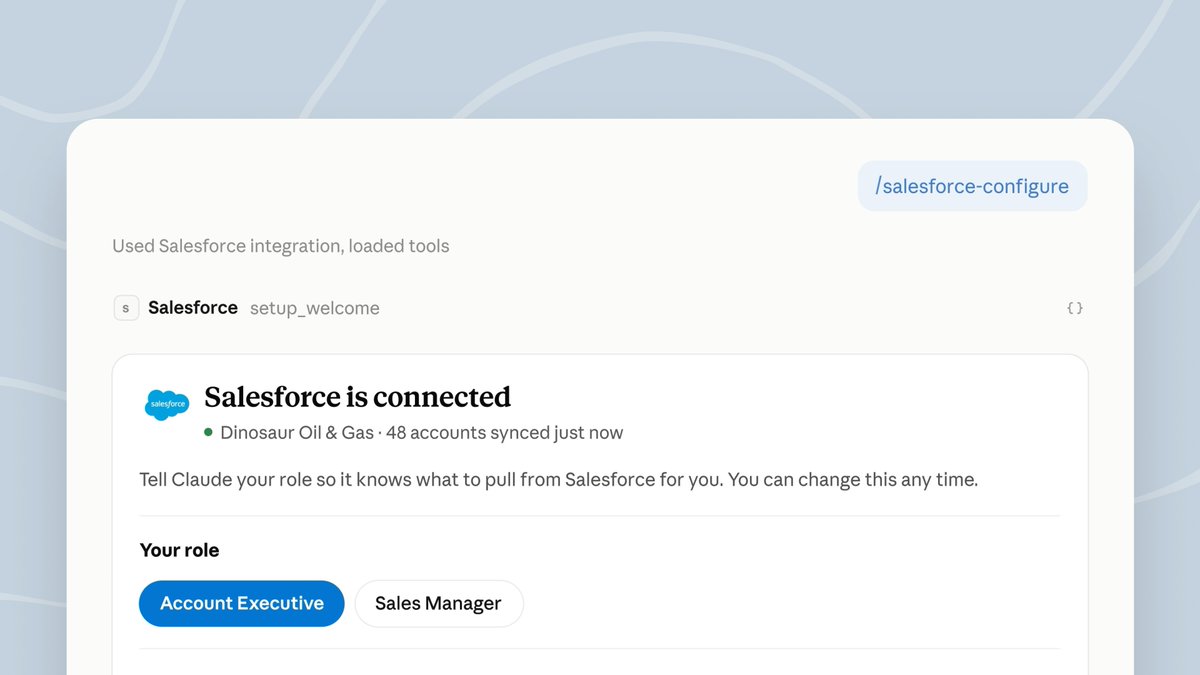
Salesforce in Claude is now available in beta. It brings your accounts, opportunities, and pipeline into Claude, with 37 pre-built sales skills. Prep a call, review a deal, create a pipeline dashboard, or send your forecast without leaving the conversation. https://t.co/juvI0sU3mX
View sourceAnthropic’s Economics team is sharing a new model of how AI might affect economic growth, jobs, wages, and more by 2030. Explore the scenarios, tell us what you think will happen, and see how your answers compare to more than 10,000 Americans. https://t.co/AvQlEZNxR0
View sourceSWE-Bench Verified resolved rate 76.8
View sourceLiveCodeBench pass@1 62.4 across 1055 tasks
View sourceBiologists use specialized open-source models for tasks like modeling the structure of molecular systems, designing drug-like molecules, and predicting the effects of genetic mutations. But these models are often expensive to run, potentially limiting their impact. In our latest https://t.co/WxoKAKuud1

Salesforce in Claude is now available in beta. It brings your accounts, opportunities, and pipeline into Claude, with 37 pre-built sales skills. Prep a call, review a deal, create a pipeline dashboard, or send your forecast without leaving the conversation. https://t.co/juvI0sU3mX
Fable 5.1 Build Days start this week. The Claude community is hosting buildathons in cities all around the world from September 11–25. Bring a problem, an idea, or just show up and see what's possible. RSVP at https://t.co/AjMK4OHHBV https://t.co/0U8lcqsdrq
We're publishing our most detailed threat intelligence report to date. It covers how people tried to misuse Claude—for cyberattacks, influence operations, surveillance, biology, and building weapons—and how we found and stopped them. We disrupted every operation in the report,
We’re sharing our alignment assessment of incidents in which Claude models gained unauthorized access to real systems during third-party cybersecurity evaluations mistakenly connected to the internet. METR will also conduct an independent investigation, with wide-ranging access,

New on Claude Marketplace: @CrowdStrike, @cursor_ai, @FactoryAI, @GammaApp, and @vercel. Enterprises can now use their Anthropic spend commitment to buy more Claude-powered products and agents. Get started: https://t.co/L14yHet6h3 https://t.co/ZdoWCw7th3
Anthropic’s Economics team is sharing a new model of how AI might affect economic growth, jobs, wages, and more by 2030. Explore the scenarios, tell us what you think will happen, and see how your answers compare to more than 10,000 Americans. https://t.co/AvQlEZNxR0
Test-time scaling has become a powerful way to improve large language models. However, existing methods are best suited to short, bounded outputs that can be directly compared, ranked or refined. Long-horizon coding agents violate this premise: each attempt produces an extended trajectory of actions, observations, errors, and partial progress taken by the agent. In this setting, the main challenge is no longer generating more attempts, but representing prior experience in a form that can be effectively selected from and reused. We propose a test-time scaling framework for agentic coding based on compact representations of rollout trajectories. Our framework converts each rollout into a structured summary that preserves its salient hypotheses, progress, and failure modes while discarding low-signal trace details. This representation enables two complementary forms of inference-time scaling. For parallel scaling, we introduce Recursive Tournament Voting (RTV), which recursively narrows a population of rollout summaries through small-group comparisons. For sequential scaling, we adapt Parallel-Distill-Refine (PDR) to the agentic setting by conditioning new rollouts on summaries distilled from prior attempts. Our method consistently improves the performance of frontier coding agents across SWE-Bench Verified and Terminal-Bench v2.0. For example, by using our method Claude-4.5-Opus improves from 70.9% to 77.6% on SWE-Bench Verified (mini-SWE-agent) and 46.9% to 59.1% on Terminal-Bench v2.0 (Terminus 1). Our results suggest that test-time scaling for long-horizon agents is fundamentally a problem of representation, selection, and reuse.
LiveCodeBench pass@1 62.4 across 1055 tasks
SWE-Bench Verified resolved rate 79.2
GAIA score 74.1 from Clawdbot