DeepSeek
We present a preview version of DeepSeek-V4 series, including two strong Mixture-ofExperts (MoE) language models — DeepSeek-V4-Pro with 1. 6T parameters (49B activated) and DeepSeek-V4-Flash with 284B parameters (13B activated) — both supporting a context length of one million tokens.
Running this yourself: likely needs a high-memory cloud gpu.
DeepSeek-V4-ProMax, the maximum reasoning effort mode of DeepSeek-V4-Pro, redefines the state-of-the-art for ope
Live access is not confirmed for this model. No current purchase price is advertised.
No current subscription pricing is tracked for this model.
Confirm this specific model, usage limits, and billing terms with the provider. A subscription does not automatically include API credits.
No login needed to compare. Prices are in USD; provider charges are separate from AI Market Cap plans. Context length, caching, tools, taxes, and regional terms can change the final cost. Open weights do not mean free hosting.
62.5
Quality Score
---
Arena ELO
284B
Parameters
1M
Context
This measures the amount of verifiable public evidence we have, not how capable the model is. A missing field means it has not been verified yet, not that its value is zero.
19 of 22 public signals
Sign in to join the discussion
1.3M
Downloads
2.3K
Likes
Apr 2026
Released
5/5 signals
3/4 signals
4/5 signals
3/4 signals
4/4 signals
Parameters
284B
Training compute
2.5e24 FLOP
Dataset scale
Not reported
Base model
Not reported
Source-reported access: Open weights (unrestricted) · Likely confidence
Gaps we are still tracking
Pricing
2
Benchmarks
4
API
1
Research
2
General
2
Recent launch, pricing, benchmark, and API signals linked to this model or its provider.
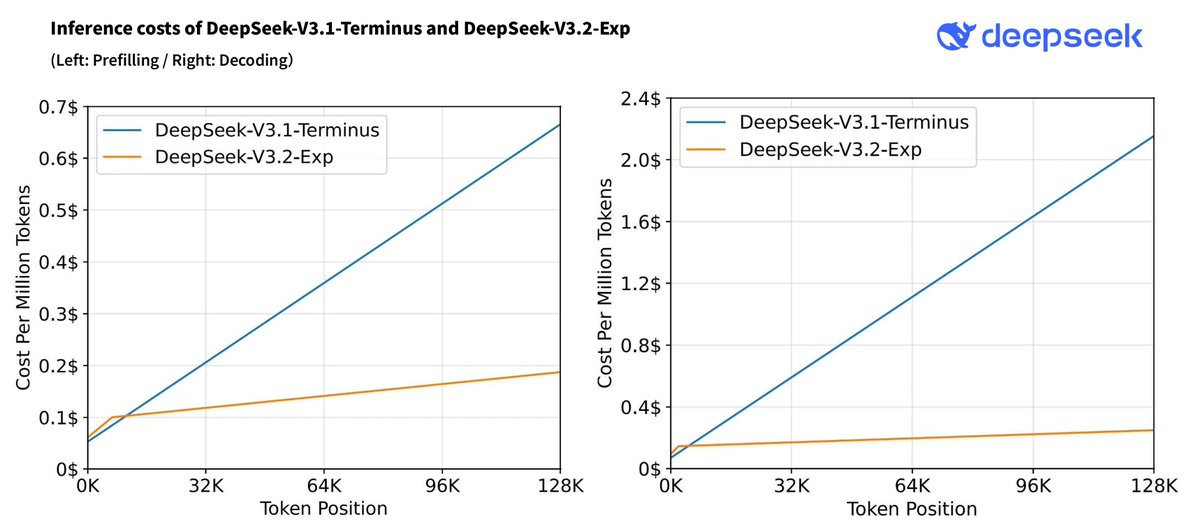
⚡️ Efficiency Gains 🤖 DSA achieves fine-grained sparse attention with minimal impact on output quality — boosting long-context performance & reducing compute cost. 📊 Benchmarks show V3.2-Exp performs on par with V3.1-Terminus. 2/n https://t.co/zTG679p5Zm
DeepSeek published benchmark or leaderboard evidence for DeepSeek-V4-Flash.
View sourceGAIA score 23.6 from deepseek-v4-flash
View source
⚡️ Efficiency Gains 🤖 DSA achieves fine-grained sparse attention with minimal impact on output quality — boosting long-context performance & reducing compute cost. 📊 Benchmarks show V3.2-Exp performs on par with V3.1-Terminus. 2/n https://t.co/zTG679p5Zm
We introduce Nemotron-Cascade 2, an open 30B MoE model with 3B activated parameters that delivers best-in-class reasoning and strong agentic capabilities. Despite its compact size, its mathematical and coding reasoning performance approaches that of frontier open models. It is the second open-weight LLM, after DeepSeekV3.2-Speciale-671B-A37B, to achieve Gold Medal-level performance in the 2025 International Mathematical Olympiad (IMO), the International Olympiad in Informatics (IOI), and the ICPC World Finals, demonstrating remarkably high intelligence density with 20x fewer parameters. In contrast to Nemotron-Cascade 1, the key technical advancements are as follows. After SFT on a meticulously curated dataset, we substantially expand Cascade RL to cover a much broader spectrum of reasoning and agentic domains. Furthermore, we introduce multi-domain on-policy distillation from the strongest intermediate teacher models for each domain throughout the Cascade RL process, allowing us to efficiently recover benchmark regressions and sustain strong performance gains along the way. We release the collection of model checkpoint and training data.
DeepSeek-V4-Flash is now available through Ollama Cloud. 1M context window listed. DeepSeek-V4-Flash is the official release of DeepSeek-V4-Flash, built for efficient reasoning across a 1M-token context window, outperforming DeepSeek-V4-Pro (Preview).
DeepSeek published benchmark or leaderboard evidence for DeepSeek-V4-Flash.
GAIA score 23.6 from deepseek-v4-flash