DeepSeek
1. DeepSeek Sparse Attention (DSA): We introduce DSA, an efficient attention mechanism that substantially reduces computational complexity while preserving model performance, specifically optimized for long-context scenarios. 2.
Running this yourself: can likely run on your own machine.
Live access is not confirmed for this model. No current purchase price is advertised.
No current subscription pricing is tracked for this model.
Confirm this specific model, usage limits, and billing terms with the provider. A subscription does not automatically include API credits.
No login needed to compare. Prices are in USD; provider charges are separate from AI Market Cap plans. Context length, caching, tools, taxes, and regional terms can change the final cost. Open weights do not mean free hosting.
68.2
Quality Score
1334
Arena ELO
Unknown
Parameters
131K
Context
This measures the amount of verifiable public evidence we have, not how capable the model is. A missing field means it has not been verified yet, not that its value is zero.
18 of 22 public signals
Sign in to join the discussion
3.5M
Downloads
1.5K
Likes
Dec 2025
Released
4/5 signals
4/4 signals
4/5 signals
3/4 signals
3/4 signals
Parameters
—
Training compute
Not reported
Dataset scale
Not reported
Base model
Not reported
Gaps we are still tracking
Launches
2
Pricing
1
Benchmarks
7
API
1
Research
3
General
2
Recent launch, pricing, benchmark, and API signals linked to this model or its provider.
SWE-Bench Verified resolved rate 60.0
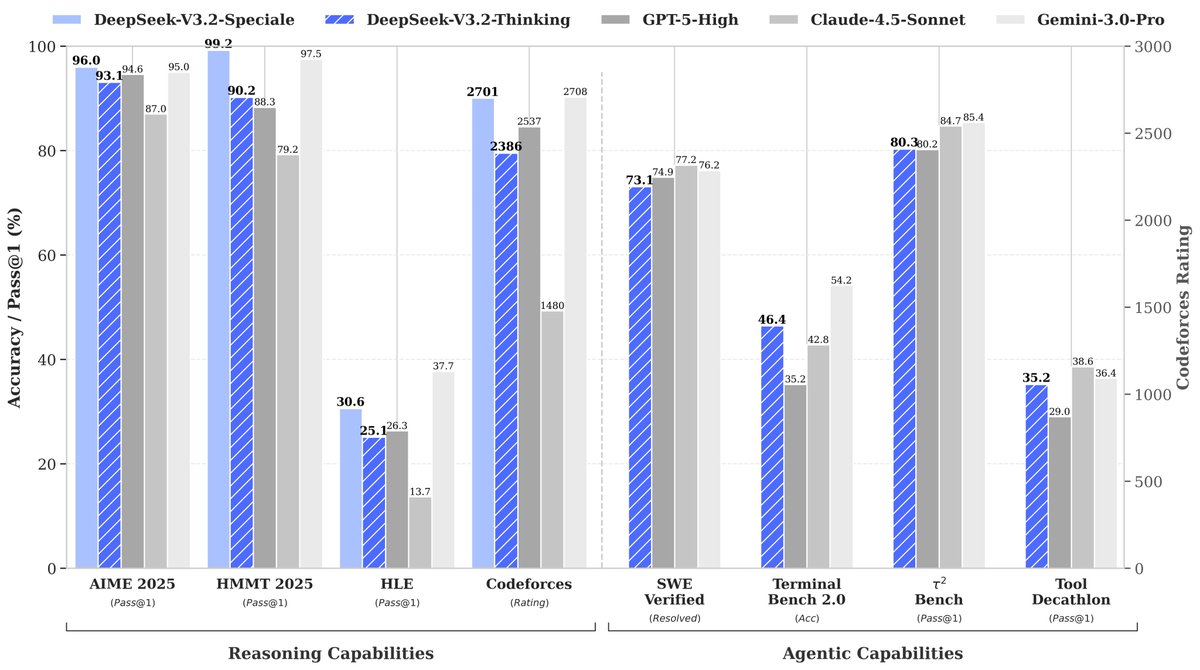
🚀 Launching DeepSeek-V3.2 & DeepSeek-V3.2-Speciale — Reasoning-first models built for agents! 🔹 DeepSeek-V3.2: Official successor to V3.2-Exp. Now live on App, Web & API. 🔹 DeepSeek-V3.2-Speciale: Pushing the boundaries of reasoning capabilities. API-only for now. 📄 Tech https://t.co/SC49UdmCZv
SWE-Bench Verified resolved rate 60.0
View sourceSWE-Bench Verified resolved rate 70.0
View source
🚀 Launching DeepSeek-V3.2 & DeepSeek-V3.2-Speciale — Reasoning-first models built for agents! 🔹 DeepSeek-V3.2: Official successor to V3.2-Exp. Now live on App, Web & API. 🔹 DeepSeek-V3.2-Speciale: Pushing the boundaries of reasoning capabilities. API-only for now. 📄 Tech https://t.co/SC49UdmCZv
DeepSeek Sparse Attention (DSA) sets the state of the art for fine-grained inference-time sparse attention by introducing a learned token-wise indexer that scores every prefix token and selects the most relevant ones for the main attention. To remain expressive, the indexer uses many query heads (for example, 64 on DeepSeek-V3.2) that share the same selected token set; this multi-head design is precisely what makes the indexer the dominant cost on long contexts. We propose MISA (Mixture of Indexer Sparse Attention), a drop-in replacement for the DSA indexer that treats its indexer heads as a pool of mixture-of-experts. A lightweight router uses cheap block-level statistics to pick a query-dependent subset of only a few active heads, and only those heads run the heavy token-level scoring. This preserves the diversity of the original indexer pool while reducing the per-query cost from scoring every prefix token with every head to scoring it with only a handful of routed heads, plus a negligible router term computed on a small set of pooled keys. We further introduce a hierarchical variant of MISA that uses the routed pass to keep an enlarged candidate set and then re-ranks it with the original DSA indexer to recover the final selected tokens almost exactly. With only eight active heads and no additional training, MISA matches the dense DSA indexer on LongBench across DeepSeek-V3.2 and GLM-5 while running with eight and four times fewer indexer heads respectively, and outperforms HISA on average. It also preserves fully green Needle-in-a-Haystack heatmaps up to a 128K-token context and recovers more than 92% of the tokens selected by the DSA indexer per layer. Our TileLang kernel delivers roughly a 3.82 times speedup over DSA's original indexer kernel on a single NVIDIA H200 GPU.
We introduce Nemotron-Cascade 2, an open 30B MoE model with 3B activated parameters that delivers best-in-class reasoning and strong agentic capabilities. Despite its compact size, its mathematical and coding reasoning performance approaches that of frontier open models. It is the second open-weight LLM, after DeepSeekV3.2-Speciale-671B-A37B, to achieve Gold Medal-level performance in the 2025 International Mathematical Olympiad (IMO), the International Olympiad in Informatics (IOI), and the ICPC World Finals, demonstrating remarkably high intelligence density with 20x fewer parameters. In contrast to Nemotron-Cascade 1, the key technical advancements are as follows. After SFT on a meticulously curated dataset, we substantially expand Cascade RL to cover a much broader spectrum of reasoning and agentic domains. Furthermore, we introduce multi-domain on-policy distillation from the strongest intermediate teacher models for each domain throughout the Cascade RL process, allowing us to efficiently recover benchmark regressions and sustain strong performance gains along the way. We release the collection of model checkpoint and training data.
SWE-Bench Verified resolved rate 70.0
DeepSeek-V3.2 is now available through Ollama Cloud. 160K context window listed. DeepSeek-V3.2, a model that harmonizes high computational efficiency with superior reasoning and agent performance.
SWE-Bench Verified resolved rate 60.0
LiveCodeBench pass@1 49.6 across 1055 tasks
SWE-Bench Verified resolved rate 70.0
GAIA score 37.2 from meta-agent