DeepSeek
DeepSeek-V2 adopts innovative architectures to guarantee economical training and efficient inference: - For attention, we design MLA (Multi-head Latent Attention), which utilizes low-rank key-value union compression to eliminate the bottleneck of inference-time key-value cache, thus supporting efficient inference.
Live access is not confirmed for this model. No current purchase price is advertised.
No current subscription pricing is tracked for this model.
Confirm this specific model, usage limits, and billing terms with the provider. A subscription does not automatically include API credits.
No login needed to compare. Prices are in USD; provider charges are separate from AI Market Cap plans. Context length, caching, tools, taxes, and regional terms can change the final cost. Open weights do not mean free hosting.
56.2
Quality Score
1273
Arena ELO
236B
Parameters
16K
Context
This measures the amount of verifiable public evidence we have, not how capable the model is. A missing field means it has not been verified yet, not that its value is zero.
18 of 22 public signals
Sign in to join the discussion
43.1K
Downloads
335
Likes
Apr 2024
Released
5/5 signals
4/4 signals
3/5 signals
3/4 signals
3/4 signals
Parameters
236B
Training compute
Not reported
Dataset scale
Not reported
Base model
Not reported
Gaps we are still tracking
Metadata sources
Pricing
2
Benchmarks
2
Open Source
1
Research
2
General
2
Recent launch, pricing, benchmark, and API signals linked to this model or its provider.
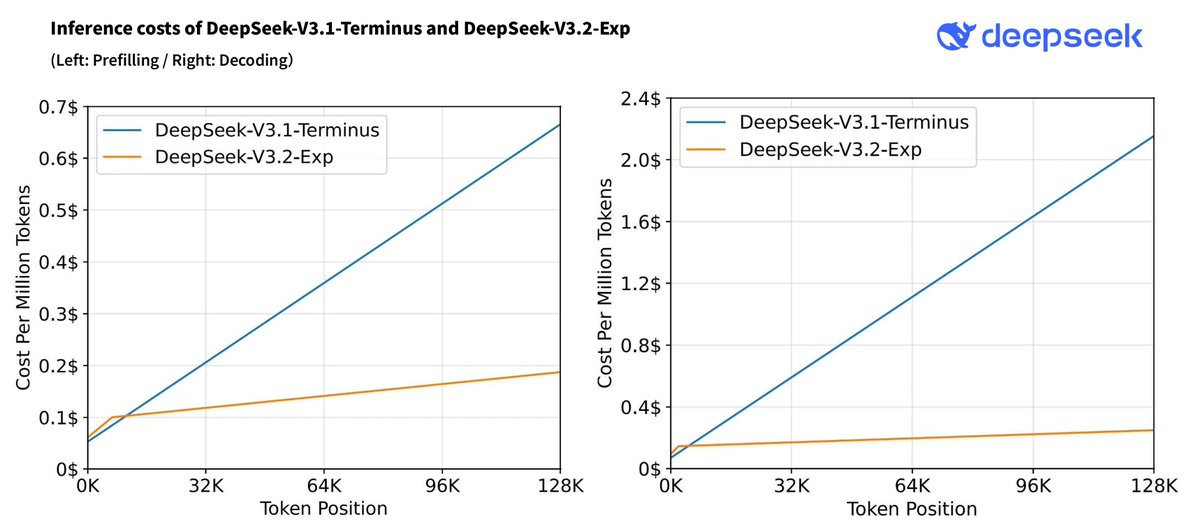
⚡️ Efficiency Gains 🤖 DSA achieves fine-grained sparse attention with minimal impact on output quality — boosting long-context performance & reducing compute cost. 📊 Benchmarks show V3.2-Exp performs on par with V3.1-Terminus. 2/n https://t.co/zTG679p5Zm
GAIA score 13.0 from deepseek
View sourceDeepSeek published benchmark or leaderboard evidence for DeepSeek-V2.
View sourceDeepSeek-V2 is now available through local Ollama runtime. 4K context window listed. An upgraded version of DeekSeek-V2 that integrates the general and coding abilities of both DeepSeek-V2-Chat and DeepSeek-Coder-V2-Instruct.
View source
⚡️ Efficiency Gains 🤖 DSA achieves fine-grained sparse attention with minimal impact on output quality — boosting long-context performance & reducing compute cost. 📊 Benchmarks show V3.2-Exp performs on par with V3.1-Terminus. 2/n https://t.co/zTG679p5Zm
We introduce Nemotron-Cascade 2, an open 30B MoE model with 3B activated parameters that delivers best-in-class reasoning and strong agentic capabilities. Despite its compact size, its mathematical and coding reasoning performance approaches that of frontier open models. It is the second open-weight LLM, after DeepSeekV3.2-Speciale-671B-A37B, to achieve Gold Medal-level performance in the 2025 International Mathematical Olympiad (IMO), the International Olympiad in Informatics (IOI), and the ICPC World Finals, demonstrating remarkably high intelligence density with 20x fewer parameters. In contrast to Nemotron-Cascade 1, the key technical advancements are as follows. After SFT on a meticulously curated dataset, we substantially expand Cascade RL to cover a much broader spectrum of reasoning and agentic domains. Furthermore, we introduce multi-domain on-policy distillation from the strongest intermediate teacher models for each domain throughout the Cascade RL process, allowing us to efficiently recover benchmark regressions and sustain strong performance gains along the way. We release the collection of model checkpoint and training data.
DeepSeek-V2 is now available through local Ollama runtime. 4K context window listed. An upgraded version of DeekSeek-V2 that integrates the general and coding abilities of both DeepSeek-V2-Chat and DeepSeek-Coder-V2-Instruct.
DeepSeek published benchmark or leaderboard evidence for DeepSeek-V2.